A hospital analyst wants to study why patients come back within 30 days. She needs ages, diagnoses and visit dates. She does not need patient names. The hospital has two ways to take the names out. It can swap each name for a code and keep the lookup table somewhere safe. Or it can strip the identifying details so completely that no one can trace a record back to a person.
Pseudonymization vs Anonymization. The first is pseudonymization. The second is anonymization. The words sound alike, but GDPR treats the results very differently. Below you will find both definitions, a side-by-side table, examples and a way to choose.
Pseudonymization meaning
Pseudonymization replaces identifying details, such as a name or an account number, with a pseudonym: a code that does not reveal who the person is. The table that links each code back to the real value is kept apart and protected. Anyone who holds that table can reverse the change, so pseudonymized data is still personal data under GDPR.
Anonymization meaning
Anonymization permanently removes or changes identifying details so a person can no longer be identified from the data. There is no key and no way back. Anonymized data is no longer personal data, so GDPR does not apply to it. The bar for genuine anonymization is strict, so be careful before you rely on it to avoid GDPR obligations.
Pseudonymization vs anonymization at a glance
| Pseudonymization | Anonymization | |
|---|---|---|
| What it does | Replaces identifiers with codes (pseudonyms) | Removes or generalizes identifiers for good |
| Can it be reversed? | Yes, with the separate key or lookup table | No |
| Personal data under GDPR? | Yes, still personal data | No, if truly anonymized |
| How useful is the data? | High: records stay linked to the same person | Lower: detail is lost |
| Best for | Research, testing, customer support, fraud prevention | Sharing with third parties, published datasets |
| Example | Jane Doe becomes User_1001 | Jane Doe, 34, becomes “patient, age 30 to 39” |
The short rule: use pseudonymization when you still need to link records to a person. Use anonymization when you never will.
Pseudonymization in practice
Pseudonymization works on any field that points to a person.
- Names: John Doe becomes User1234.
- Addresses: a street address and postal code become a code, and you keep only the general region if you need it.
- Identification numbers: Social Security numbers and national ID numbers become random values.
- Medical data: patient IDs and record numbers become codes, so each diagnosis stays tied to the same patient.
- Financial data: bank account and card numbers become tokens.
Worked example: pseudonymizing transactions
A finance team wants to test a fraud model on real transactions, but analysts should not see real names or account numbers. This is the original data:
| Name | Account number | Amount |
|---|---|---|
| Jane Doe | 48151623 | $12,400 |
| Raj Patel | 91827364 | $3,950 |
| Jane Doe | 48151623 | $860 |
And this is the pseudonymized copy the analysts get:
| Name | Account number | Amount |
|---|---|---|
| User_1001 | ACC_7Q2X9 | $12,400 |
| User_1002 | ACC_M40B1 | $3,950 |
| User_1001 | ACC_7Q2X9 | $860 |
Both of Jane’s rows get the same codes, so analysts can still group and count her transactions. The lookup table that maps User_1001 back to Jane Doe stays in a separate system that only a few authorized people can open. That is why the data is useful and still counts as personal data.
Benefits of pseudonymization
- Lower exposure: if the working copy leaks, it does not reveal names on its own.
- Safer sharing: teams or partners can work with the data while authorization controls protect the lookup table.
- Usable analysis: records stay linked, so detailed analysis still works. That matters most in medical, financial and research work.
- Compliance support: many privacy rules require data controllers and processors to protect personal information, and pseudonymization helps with GDPR, HIPAA and others.
Related reading: How Pseudonymization Can Be Key to A Robust Data Privacy Strategy
Anonymization in practice
Picture a city health department that wants to publish hospital visit counts for researchers. It cannot publish names. It also should not publish anything that lets a neighbor work out who was sick. That is the job anonymization does.
Common candidates are demographic data (age, gender, location), financial transactions, healthcare data (test results, diagnoses, treatments), web browsing and search history, and survey responses.
Whether you can anonymize a dataset depends on its type and size. Some data cannot be fully anonymized and still stay useful for analysis or research. Rare combinations, such as an unusual diagnosis in a small town, can point to one person even after the names are gone.
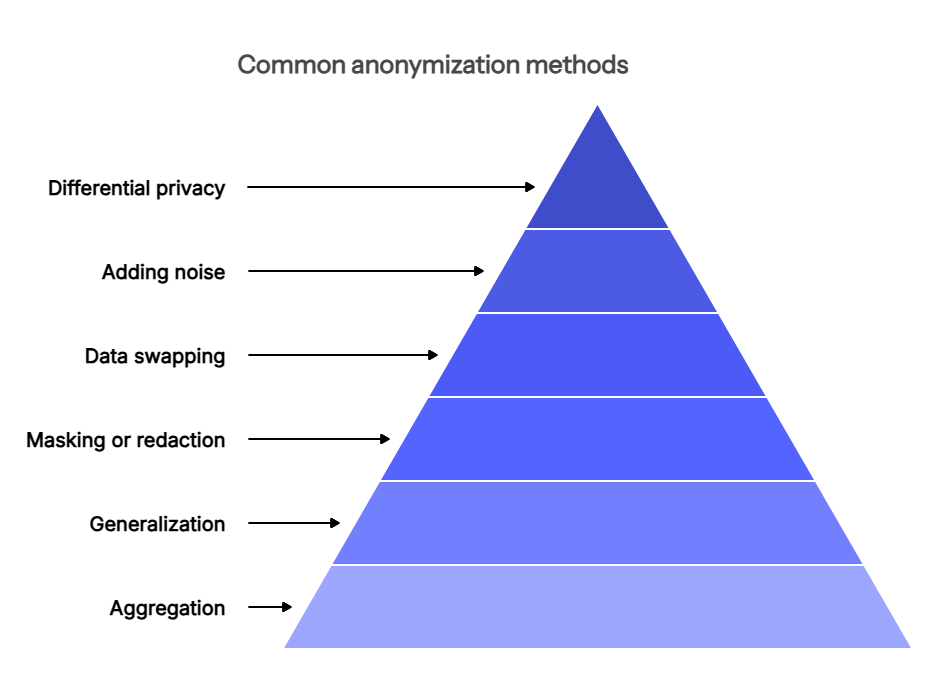
Common anonymization methods
- Aggregation: group individual data points. Instead of each customer’s age, share ranges like 20 to 30 and 30 to 40.
- Generalization: make a value less precise. Replace an exact income with a bracket ($50,000 to $60,000), or a city with a state.
- Masking or redaction: delete the value, such as a Social Security number, email address or phone number. Replacing it with a reversible code is pseudonymization, not anonymization.
- Adding noise: make small random changes that hide specific values and keep the overall statistics.
- Data swapping: exchange values between records, so the dataset keeps its structure but a row no longer describes one real person.
- Differential privacy: a formal framework that adds controlled noise and gives a measurable privacy guarantee while keeping the data useful.
Worked example: anonymizing patient data
A clinic wants to share patient data with a research partner. This is the original:
| Name | Age | ZIP code | Diagnosis |
|---|---|---|---|
| Jane Doe | 34 | 94110 | Asthma |
| Raj Patel | 41 | 94117 | Diabetes |
And this is the anonymized version:
| Age range | Region | Diagnosis |
|---|---|---|
| 30 to 39 | 941** | Asthma |
| 40 to 49 | 941** | Diabetes |
Names are gone, ages became ranges, and ZIP codes lost their last two digits. Nothing maps a row back to Jane. With only two rows, though, someone who knows Jane’s age and neighborhood could still guess which row is hers. Real projects check that every combination of age range and region matches several people before they call the data anonymized.
Related reading: Data Anonymization’s Critical Role in Protecting Data Privacy
GDPR: how pseudonymized and anonymized data are treated
GDPR treats the two differently. The difference is the first thing to settle before you choose a method. For the regulation itself, see our GDPR compliance page.
Pseudonymized data
Pseudonymized data remains personal data, because it can be re-identified with additional information. All GDPR obligations still apply to it. GDPR recognizes pseudonymization as a mechanism for security and for data protection by design, and proper pseudonymization can reduce some of a controller’s legal obligations to a certain extent.
Anonymized data
Truly anonymized data is not personal data and falls outside GDPR. The criteria are so strict that a controller should be very careful before using anonymization to avoid GDPR obligations altogether.
Pseudonymization vs encryption
Encryption scrambles data with a cryptographic key, so it stays unreadable until someone decrypts it. Pseudonymization replaces the identifiers and leaves the rest of the data readable and usable. The two can be used together.
Which should you use: pseudonymization or anonymization?
A support agent needs to look up a customer’s order. A data scientist needs buying patterns across ten thousand orders. The agent has to know who the customer is. The data scientist does not. That one difference usually settles the choice.
- Use pseudonymization when you still need identifiers for business work, such as customer service, fraud prevention, or research that follows the same people over time.
- Use anonymization when you will never need to go back to the person, and the data will be shared widely or published.
Teams inside one company often choose differently. Customer support may need reversible pseudonymization to see the right customer. A software testing team may get by with anonymized data if it never needs to link records. Different teams also favor different data masking techniques. When you are unsure, start with the method that reveals less, then add back only what the work needs.
These choices matter more once data feeds AI systems. A prompt, a vector index or an agent’s memory can copy personal data into places a lookup table does not reach. Our guide to AI data protection covers how to keep control there.
How tokenization fits in
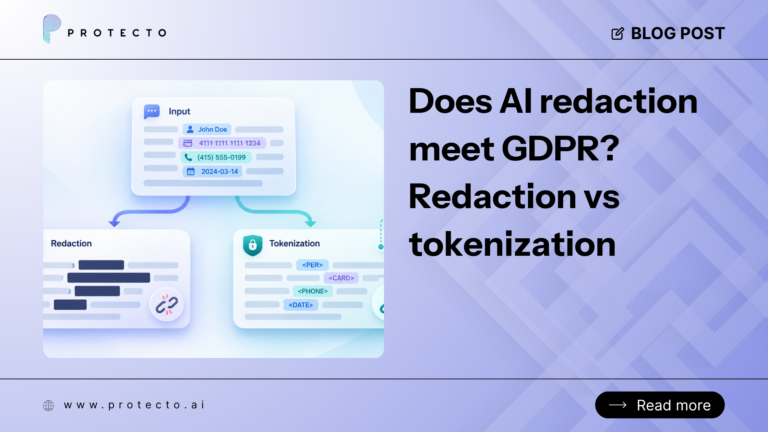
Tokenization replaces a sensitive value, such as a card number, with a randomly generated token that is not derived from the original. The link between the two sits in a secure token store.
In most setups, tokenization is a form of pseudonymization. The token stands in for the real value and can be mapped back through the token store, but only by people or systems with access. Tokenization can support anonymization only when no link back exists: the tokens have no retraceable connection to the original data, and nothing else in the dataset can re-identify the person.
Take a payment system. Instead of storing card numbers, it stores a token for each one. The real numbers live in a separate, secured location. If the tokenized data is breached, it is of little use without access to that location.
To go deeper on how it works, read our data tokenization guide or our post on how to protect sensitive data with data tokenization.
Protecto’s Intelligent Tokenization
Say your support team wants an AI assistant to work through customer tickets. The tickets contain names, email addresses and account numbers. You want the model to understand the ticket, but not to see who the customer is.
Protecto’s Intelligent Tokenization replaces those values with tokens before the text reaches the model. The same person gets the same token in every ticket and document, so the assistant can still follow who did what. When policy allows it, an authorized user or system can turn a token back into the original value.
- It protects personal data in both structured data and free text.
- Tokens can keep the format of the original value, so downstream systems keep working.
- It supports GDPR, HIPAA and CCPA programs.
- It deploys as SaaS, on-premise, in a private cloud, or air-gapped.
To see it on your own data, schedule a demo.
Frequently asked questions
What is the difference between pseudonymization and anonymization?
Pseudonymization replaces identifiers with codes and keeps a separate key, so the data can be re-identified. Anonymization permanently removes identifiers, so the data cannot be traced back to a person. Under GDPR, pseudonymized data is still personal data. Truly anonymized data is not.
Is pseudonymized data personal data under GDPR?
Yes. Pseudonymized data can be re-identified with additional information, so GDPR still treats it as personal data and its obligations still apply. Pseudonymization is a recognized safeguard that can reduce some of those obligations to a certain extent.
Can anonymized data be re-identified?
Truly anonymized data cannot be traced back to a person, because there is no key to reverse it. The risk is data that is only partly anonymized. If a rare mix of details, such as age, location and diagnosis, still points to one person, the data is not truly anonymous.
Which is better, pseudonymization or anonymization?
Neither wins in every case. Use pseudonymization when you still need to link records to a person, as in customer support, fraud checks or research over time. Use anonymization when you will not need to go back to the person and the data will be shared widely or published.
Is tokenization pseudonymization or anonymization?
Usually pseudonymization. A token can be mapped back to the original value through a secure token store, so the data remains personal data under GDPR. If no link back exists and nothing else in the data can re-identify the person, tokenization can support anonymization.