
RAG indexes, embedding jobs and ETL runs can copy PII and PHI before any policy checks it. Protecto masks that data first and keeps the context your AI needs.
SOC 2 Type II · ISO 27001 · HIPAA, BAA available
Long texts processed per day at the SaaS company
Claims documents in scope at a healthcare data platform
Below the in-house cost estimate at the SaaS company
A data engineer adds a year of support tickets to a nightly embedding job so the assistant can answer better. Some tickets hold names, dates of birth and claim numbers. By morning those values sit in the vector index, and a routine question can pull them into a model.
Your controls guarded the source. The copy left without them.
Permissions, DLP scans and access reviews guard the source. Once text is embedded or handed to an agent, they can’t show what the AI used.
Blanking fields or whole chunks looks safer, but search loses the people, claims and dates that tied the data together.
Table permissions show who could read the source. They don’t show which values were masked, embedded or revealed later.
Pick a stage and switch Protecto on. Watch where real values end up, and what the AI still gets to work with.
Synthetic example. Your policy decides what gets masked.
See this on a pipeline of your own.
Call Protecto from the step that already moves the data: ingestion, ETL, embedding or an agent. Use the API, a Snowflake UDF, Databricks, Kafka or Spark. Send text, get tokens back, pass them on.
The output is still text, so your vector database, framework and model stay as they are. For large batches, submit an async job and collect the result when it finishes.
Request
PUT /api/vault/mask
{"mask": [{"value": "Maya Shah called about claim CLM-88291 after her asthma follow-up."}]}
Response: token_value
<PER>0AmY 0AcJ</PER> called about claim <CLAIM_ID>Bicnh</CLAIM_ID> after her asthma follow-up.
Synthetic example. Your policy decides what gets masked.
One clinical note, two ways to protect it before indexing. Only one keeps the meaning search depends on.
| What the pipeline needs | Drop or redact | Protecto tokens |
|---|---|---|
| The chunk text | Patient [REDACTED] seen for [REDACTED]. | Patient <PER>0AmY 0AcJ</PER> seen for asthma follow-up. |
| Search can find it | Poorly. The condition can go too. | Yes. The context stays in clear text. |
| Records stay distinct | No. Every patient looks the same. | Yes. Same value, same token. |
| Real values come back | No. They are gone from this copy. | By role, with a log entry. |
Synthetic example. Your policy decides what stays in clear text. A healthcare data platform used this approach to prepare about 750M claims documents in scope for AI search, summarization and analytics. A large technology company uses Protecto’s API to detect and mask sensitive values in telemetry, operational logs and partner data. Read the telemetry case study
Tokens are the output. Around them you need detection you can trust, room for volume, access rules and proof.
50+ entity types across PII, PHI and PCI, plus custom entities, officially tested in seven languages.
Async APIs, queuing and batches handle the backfill as well as the nightly run. One SaaS company processes 13M+ long texts a day.
Context-Based Access Control (CBAC) decides who sees real values. Everyone else keeps seeing tokens.
Event logs record each mask and reveal. Reports show where sensitive data flows and how your data policies were enforced.
“Protecto enabled us to deliver data security, privacy, and compliance for our AI features at scale across 5,000+ enterprise clients, strengthening customer trust in our AI automation solutions.”
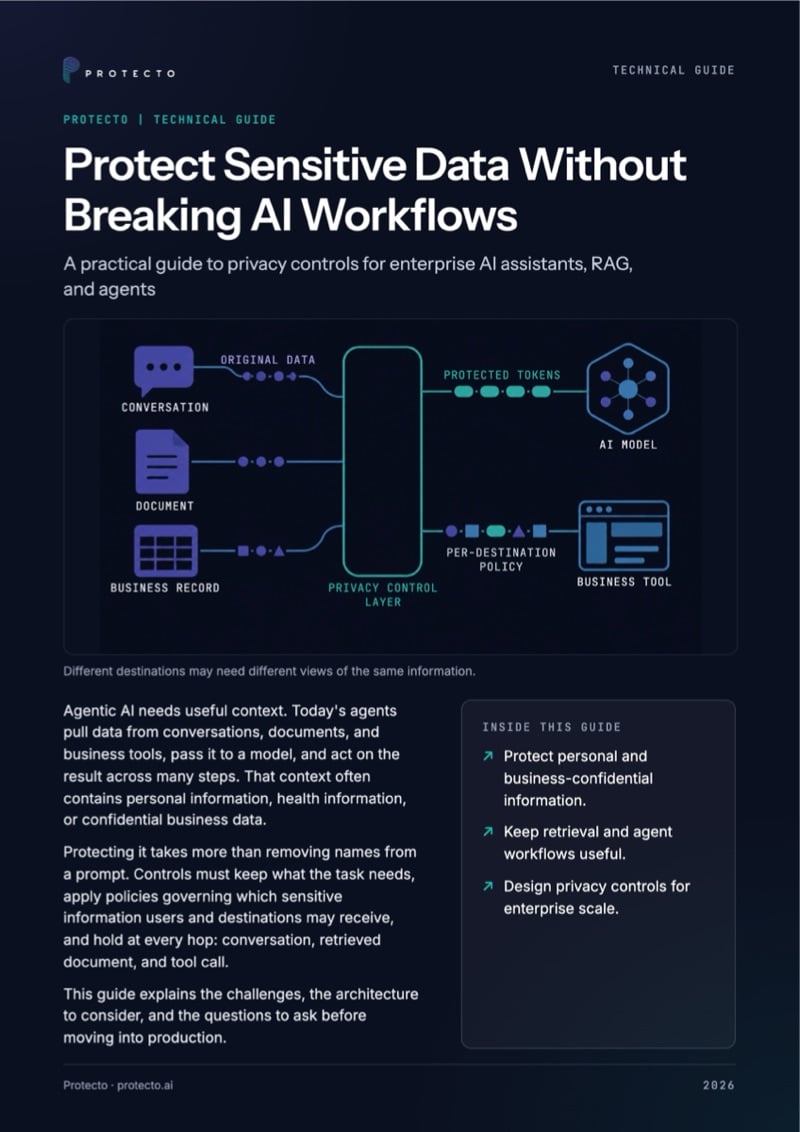
How to set a policy per destination for assistants, RAG, and agents, with a checklist for production.
How to protect personal data before, during and after model use.
An independent benchmark by UT Dallas and DataXpert, with results by entity type.
Mask PII with consistent tokens before you embed, and mask questions the same way.
At ingestion, in ETL jobs, during embedding, in RAG indexes, in API payloads, in vector database writes and in agent context. Protecto masks the data before those systems use it.
It can when placeholders carry no meaning. Protecto replaces each value with a consistent token and leaves the surrounding context in place, so search and the model have what they need.
On your servers or in your private cloud, or as SaaS. When Protecto runs in your environment, token mappings and keys stay on your servers.
Your job calls the Protecto API at the step you choose, before data reaches an index, a model or an agent. The output is still text, so downstream tools keep working as they do today.
For data pipelines, Protecto runs through its API, a Snowflake UDF, Databricks, Kafka or Spark. For AI apps, it works with LangChain, LlamaIndex and any LLM provider. Because Protecto returns text, it also works with whichever vector database you run.
Submit an async job and receive a tracking ID, check its status, and read the result when it finishes. Async APIs need a paid plan. Book a demo and we will set up a proof of concept or trial for your volume.
Yes, by policy. Pipelines run on tokens by default, and approved people and systems can get real values back based on role. Each reveal is logged.
Protecto Vault is a headless API, so integrating it means calling the API from your job. A health analytics company ran its proof of concept in under a week. Book a demo and we will scope one for your pipeline.
No. DLP keeps guarding the channels it covers. Protecto covers the AI traffic and unstructured data flowing to models and agents, and works alongside it.
Usually, yes. Tokenization is pseudonymization, not anonymization: while a mapping exists, a token can be linked back to a person. Your counsel decides what that means for each AI path. This is not legal advice.
Bring a sample, with test data if you prefer. In 30 minutes, we will show you what each step of your pipeline receives.
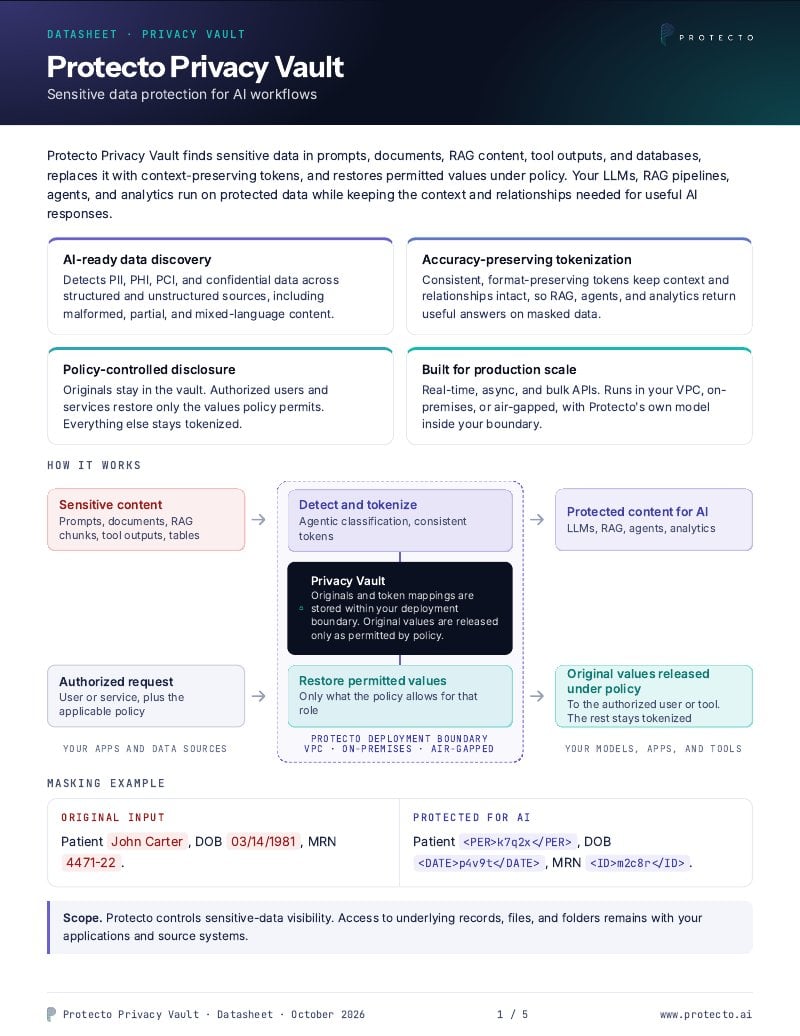
Features that safeguard your data across agents, AI applications, RAG pipelines, MCPs, data lakes, and enterprise systems.
By submitting you agree to Protecto’s privacy policy.
A practical guide to privacy controls for AI assistants, RAG, and agents. One workflow traced from request to CRM update, with what each destination may see.
By submitting you agree to Protecto’s privacy policy.
A third-party study compares how accurately Protecto, Microsoft Presidio, and AWS Comprehend find personal and health data in unstructured text.
By submitting you agree to Protecto’s privacy policy.