
Protecto swaps PII and PHI for consistent tokens before they land in your lake. A customer keeps one token in every table, so joins, BI and AI keep working.
SOC 2 Type II · ISO 27001 · HIPAA, BAA available
Long texts processed per day at the SaaS company
Lower cost than the SaaS company’s in-house estimate
Records protected at a healthcare insurer
The CRM load tokenizes customer emails. The billing job tokenizes the same emails with its own tool. On Monday, the churn report joins the two tables and comes back empty. By Friday, someone has asked for the raw table back, just for this quarter.
The data was protected, and nobody could use it.
When each pipeline tokenizes on its own, joins, group-bys and distinct counts go wrong, often with no error to warn anyone.
A job that expects a 10-digit phone number fails on a placeholder. Teams then add exceptions or leave the column unprotected.
Support and fraud teams sometimes need the real value. With no governed way to get it, nobody can show who saw what, or why.
Two tables and one query. Switch how the tables were tokenized, then watch which customers still connect.
SELECT email, plan, SUM(amount) FROM crm_customers c JOIN invoices i ON c.email = i.email GROUP BY email, plan;
crm_customers
invoices
Revenue report
Event log: unmask, fraud_reviewer, 3 values
Synthetic example. Select a row to trace one customer. In Protecto, the same value gets the same token when the same token type is used.
See this on tables of your own.
A policy sets what gets detected and how each value is replaced. Use a token where a stable string is enough, and a format-preserving value where a job checks length or pattern.
Free text gets the same treatment. Protecto finds the name inside a notes field and leaves the rest of the sentence in place.
One row, one policy
maya.shah@example.com
<EMAIL>kAywW@ueS8y</EMAIL>
4155550198
<PHONE>8349201756</PHONE>
Enterprise
Maya Shah asked about her invoice.
<PER>0AmY 0AcJ</PER> asked about her invoice.
Synthetic example. Your policy decides what gets tokenized and how.
Call Protecto from the step that already moves the data, using its API, a Snowflake UDF, Databricks, Kafka or Spark. Tables keep their structure, so downstream jobs keep reading the same columns.
For tables already in the lake, submit an async job and collect the result when it finishes.
Request
PUT /api/vault/mask
{"mask": [{"value": "maya.shah@example.com"}]}
Response: token_value
<EMAIL>kAywW@ueS8y</EMAIL>
Synthetic example. Send the same email with the same token type from any job and you get the same token back.
Three ways to protect the same column. The difference is what your queries can still do afterward.
| What your lake needs | Redaction | Encryption | Protecto tokenization |
|---|---|---|---|
| Join and group by the column | Every value looks the same. | Usually not. The output often differs each time. | Same value, same token. |
| Query without restoring values | Only the fields left behind. | Queries need the data decrypted. | Queries run on the tokens. |
| Pass length and pattern checks | Placeholders fail the check. | Usually not. | With a format-preserving policy. |
| Keep free text useful for AI | Who is who gets lost. | The text is unreadable. | Context stays, and each entity stays distinct. |
| Get the real value back | Gone from this copy. | Anyone holding the key. | On explicit request, by policy and permission. |
Encryption still belongs on your storage and network. Tokenization covers what happens when people and jobs read the data.
Tokens are one part. Protecto also finds the sensitive values, handles the volume, applies your policy and keeps the records.
50+ entity types across PII, PHI and PCI, plus custom entities, officially tested in seven languages.
Async APIs, queuing and batches handle the tables you already have as well as each new load.
Pseudonymization lets approved roles request real values. An anonymization policy turns unmasking off for good, with no change to your calls.
Event logs record each mask and unmask. Reports show where sensitive data flows and how your data policies were enforced.
“Protecto enabled us to deliver data security, privacy, and compliance for our AI features at scale across 5,000+ enterprise clients, strengthening customer trust in our AI automation solutions.”
It replaces a sensitive value, such as an email, with a non-sensitive stand-in called a token. Jobs can store and process the token in place of the value. In Protecto, the same value gets the same token when the same token type is used, and the real value comes back only on an explicit, permitted request.
Masking is the goal: hiding the real value. Tokenization is one way to do it, and it keeps each value distinct and reversible under policy. Redaction is another way, and it removes the value for good.
Equality joins, group-bys, distinct counts and exact-match filters work, because one value always maps to one token. Range filters, sorting and partial matches on the real value do not, so leave those columns out of the policy or run that work on an approved, unmasked path.
Dynamic masking controls what a query returns inside that platform, and the stored values stay real. Tokenizing first means the tables and the copies made from them hold tokens. The two can work side by side.
Run a backfill. Submit an async job, receive a tracking ID, check its status and read the result when it finishes. Async APIs need a paid plan. Book a demo and we will set up a proof of concept or trial for your volume.
On your servers or in your private cloud, or as SaaS. When Protecto runs in your environment, token mappings and keys stay on your servers.
Protecto runs in data pipelines through its API, a Snowflake UDF, Databricks, Kafka or Spark. Because the output is still data your tables can hold, downstream BI and ML tools read it as they do today.
Yes. Tokens keep each person and account distinct, and the surrounding text stays in place, so a model can still reason over it. See how this works in secure AI data pipelines.
Only approved people and systems. Unmasking never happens automatically. It takes an explicit request, a policy that allows it and sufficient permissions. The stored data does not change, and each request is logged.
Usually, yes. Tokenization is pseudonymization, not anonymization: while a mapping exists, a token can be linked back to a person. Your counsel decides what that means for each dataset.
Bring a sample, with test data if you prefer. In 30 minutes, we will show you which joins, reports and jobs keep working.
This datasheet outlines features that safeguard your data and enable accurate, secure Gen AI applications.
By submitting you agree to Protecto’s privacy policy.
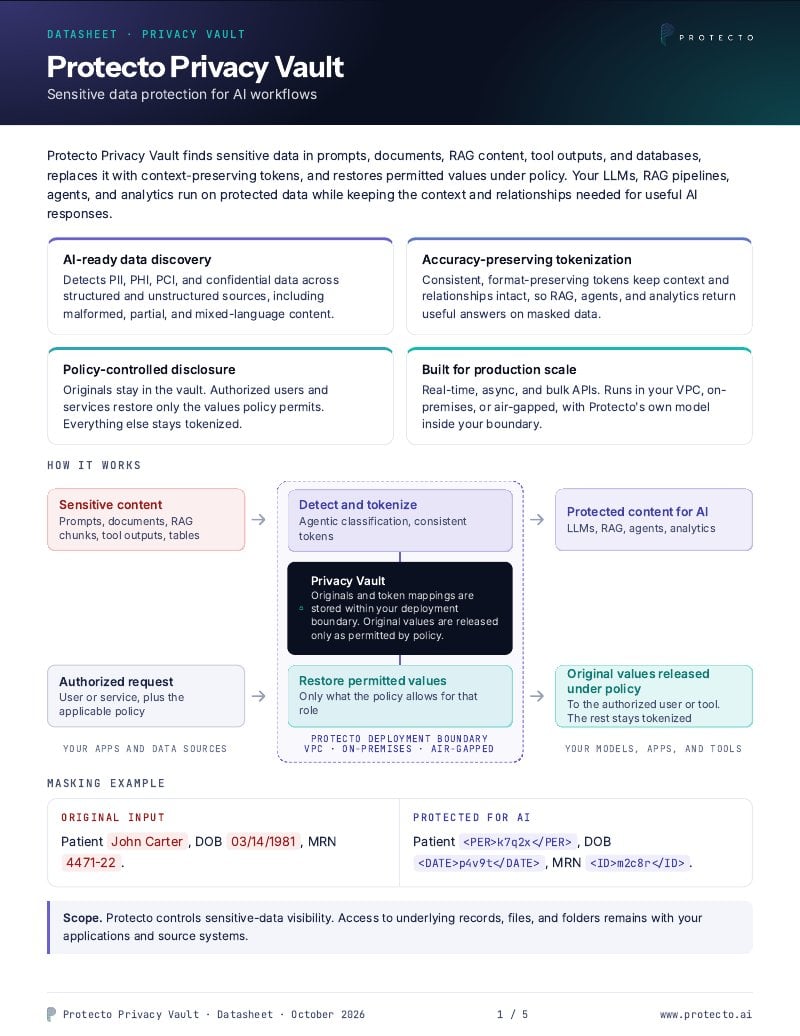
Features that safeguard your data across agents, AI applications, RAG pipelines, MCPs, data lakes, and enterprise systems.
By submitting you agree to Protecto’s privacy policy.