Data de-identification is the process of removing or replacing the details in a dataset that point to a specific person, such as names, ID numbers, contact details and exact dates, so the data can be used for analytics, research or AI with less privacy risk. Depending on the method, the change can be reversible for approved users (pseudonymization) or permanent (anonymization).
Here is a simple example. A support team exports a ticket to build a dataset:
Before
Maria Lopez (maria.lopez@acme.com) says card 4111 1111 1111 1111 was charged twice. Maria asked for a refund.

After
<PERSON>Qm7xK2</PERSON> (<EMAIL>v8rt3p@d2xk.com</EMAIL>) says card <CARD>4000 0012 7735 1094</CARD> was charged twice. <PERSON>Qm7xK2</PERSON> asked for a refund.
The complaint is still readable. The customer is still one person across the record. But the name, email and card number no longer reveal who she is.
Key takeaways
- De-identification is the goal. Masking, tokenization, generalization and suppression are ways to reach it.
- Removing names is the easy part. Quasi-identifiers and identifiers hidden in free text cause most failures.
- HIPAA, GDPR and CCPA each define de-identified data differently, so one method rarely satisfies every law.
- For analytics and AI, consistent tokens keep relationships in the data while the identities disappear.
Direct identifiers vs quasi-identifiers
Every de-identification project deals with two kinds of identifiers.
- Direct identifiers point to one person on their own: a name, Social Security number, email address, phone number or medical record number.
- Quasi-identifiers do not identify anyone alone, but they can in combination. ZIP code, birth date and sex together were enough to single out about 63% of the US population in an analysis of 2000 Census data (Golle, 2006).
A third group matters more every year: identifiers written inside free text. A support ticket, clinical note or call transcript can hold a name and a phone number in the middle of a sentence, where column-based rules never look.
De-identification vs anonymization vs pseudonymization
These terms get mixed up. De-identification is the umbrella term. Pseudonymization and anonymization are two ways to do it, and the difference is whether anyone can get the real values back.

| Term | What happens to identifiers | Can the data be traced back? | Typical use |
|---|---|---|---|
| De-identification | Removed or replaced by any method | Depends on the method | The general goal |
| Pseudonymization | Replaced with tokens or codes; the mapping is kept separately | Yes, by approved users with access to the mapping | Internal analytics, model training, records that may need follow-up |
| Anonymization | Removed or replaced with no mapping kept | Not by design, though weak anonymization can still be linked to other data | Data shared outside the organization or published |
One legal point matters here. Under GDPR, pseudonymized data is still personal data, because it can be linked back to a person. Only data that is truly anonymous falls outside GDPR. For deeper comparisons, read de-identification vs anonymization and pseudonymization vs anonymization.
Data de-identification methods

Each method trades privacy against how useful the data stays. Most real datasets combine several.
| Method | What it does | Reversible? | Best for |
|---|---|---|---|
| Suppression (redaction) | Deletes the value or replaces it with a placeholder such as [REDACTED] | No | Values nobody needs; documents released outside |
| Masking | Hides part or all of a value, such as **** **** **** 1111 | Usually no | Display and support screens |
| Tokenization | Replaces each value with a token; consistent tokenization gives the same value the same token everywhere | Yes, if a protected mapping is kept | Analytics, joins across tables, AI training, LLM prompts |
| Format-preserving replacement | Swaps a value for one in the same format, such as a valid-looking card number or date | Depends on the setup | Pipelines, schemas and validators that expect real formats (see why preserving data structure matters) |
| Generalization | Makes values less precise: age 34 becomes 30 to 39, a date becomes a year | No | Research and reporting; the basis of k-anonymity |
| Date shifting | Moves all dates for one person by the same random offset | Only with the offset | Healthcare and time-series data where intervals matter |
| Perturbation (noise) | Adds small random changes to numbers | No | Statistics where totals matter more than single records |
| Hashing | Applies a one-way function to a value | No, but weak without a secret salt | Matching records without revealing them |
A note on pseudonymization: replacing direct identifiers with codes does not, on its own, de-identify a dataset. Quasi-identifiers and free text stay in place, so combine it with generalization and free-text detection. For how masking compares, read data masking vs de-identification.
Encryption protects data from people without a key, but it is not de-identification. Anyone with the key sees the original values, and encrypted fields cannot be analyzed as they are.
You may also see three privacy-enhancing techniques listed next to these methods. Synthetic data generation builds artificial records that follow the statistical patterns of the real ones, so the output holds no real records by design. Homomorphic encryption lets a system compute on encrypted values without decrypting them. Secure multiparty computation lets several organizations analyze their combined data without any of them seeing the others’ records. They fit specific research and collaboration projects, but they are slower and harder to apply to large, mixed datasets, so most teams still de-identify the data itself.
How to de-identify data, step by step
- Decide what the data is for. Training a model, sharing with a partner and running internal reports need different levels of protection.
- Find the identifiers. Check structured columns and free text. Notes, tickets, emails and logs often hold names, phone numbers and account numbers that column rules miss.
- Include quasi-identifiers. ZIP code, birth date and gender are harmless alone but can identify a person together.
- Pick a method per field. Use tokens where relationships matter, generalization for dates and locations, and suppression for values nobody needs.
- Choose reversible or permanent. Keep a protected mapping only if approved users truly need real values back, and log every reveal.
- Run it in the pipeline. De-identify as data moves into the warehouse, lake or training job, so raw copies do not spread.
- Test the result. Check that no identifiers are left in free text, try to link the output with other data you hold, and confirm the data still answers the questions it was meant for.
For health data, follow our PHI de-identification checklist, and see how to de-identify medical records field by field and in clinical notes.
How privacy laws define de-identified data
Each law sets its own bar. Data that counts as de-identified under one can still be personal data under another.
HIPAA: Safe Harbor and Expert Determination
HIPAA allows two ways to de-identify protected health information. Data de-identified either way is no longer PHI under HIPAA.
Safe Harbor means removing 18 types of identifiers and having no actual knowledge that the remaining data could identify a person. The 18 HIPAA identifiers are:
- Names
- Geographic units smaller than a state, including street address, city, county and ZIP code (the first three ZIP digits may stay if that area holds more than 20,000 people)
- All parts of dates related to a person, except the year, and all ages over 89
- Phone numbers
- Fax numbers
- Email addresses
- Social Security numbers
- Medical record numbers
- Health plan beneficiary numbers
- Account numbers
- Certificate and license numbers
- Vehicle identifiers and serial numbers, including license plates
- Device identifiers and serial numbers
- Web URLs
- IP addresses
- Biometric identifiers, such as fingerprints and voiceprints
- Full-face photos and comparable images
- Any other unique identifying number, characteristic or code
Expert Determination means a qualified expert applies statistical methods and documents that the risk of re-identification is very small. It allows more detail to stay in the data than Safe Harbor, which helps research and analytics.
A limited data set, which keeps some dates and location details, is still PHI and needs a data use agreement. For the full HIPAA picture, read de-identification of PHI under HIPAA, and for quick answers, our HIPAA de-identification FAQ.
Clinical notes are the hard part. Many identifiers sit inside free text, where column rules never look. See how Protecto handles PHI de-identification for data lakes and HIPAA compliance.
GDPR
Anonymous data falls outside GDPR. Pseudonymized data stays in scope, because whoever holds the key can link it back to a person. GDPR still rewards pseudonymization as a security measure, and it lowers risk when data is shared.
CCPA and CPRA
California treats data as deidentified only when the business takes reasonable technical measures, publicly commits not to re-identify it, and requires recipients by contract to do the same.
This section summarizes privacy laws. It is not legal advice.
Can de-identified data be re-identified?
Yes, if it is done poorly. The common ways it happens:
- Linking datasets. Someone matches quasi-identifiers such as ZIP code, birth date and gender against another dataset that has names.
- Leftovers in free text. A name or phone number survives inside a note because only the name column was masked.
- Exposed mappings. With pseudonymized data, anyone who gets the token mapping can reverse it.
- Rare values. A rare diagnosis or job title in a small town can point to one person.
The fixes follow from the causes: detect identifiers in free text, generalize quasi-identifiers, keep any mapping in a separate protected store with access by policy, and test the output before you release it.
De-identification for AI training
AI teams want to train and fine-tune models on real tickets, chats, notes and contracts, because that is where the useful patterns are. The same records hold names, account numbers and confidential deal terms. A model trained on raw data can memorize those values and repeat them later.
Redaction makes the data safe but strips the signal: when every person becomes [REDACTED], the model cannot tell customers apart. Consistent, format-preserving tokens keep the relationships and structure while the identities disappear. Protecto-tokenized data can be treated as synthetic data. The difference is that synthetic data generators insert alternate values, while Protecto replaces each real value with a token that keeps its format and stays the same everywhere.
Training data is one of four places personal data enters an AI system, and each needs its own control:
- Training and fine-tuning data. De-identify before training so the model cannot memorize real identities.
- RAG sources. De-identify documents before they are chunked and embedded. Once personal data sits in a vector store, it is hard to find and remove.
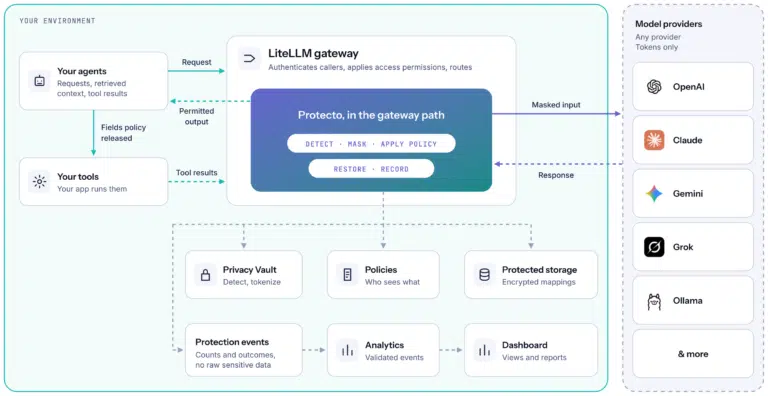
- Prompts and AI agent context. Replace sensitive values with tokens before they reach the model, and restore real values only for users allowed to see them.
- Logs and evaluation sets. Replayed conversations and evaluation data carry the same personal data as production.
For clinical text with no fixed pattern, see how to de-identify PHI in AI workflows. Learn how this works for training datasets in AI training data de-identification, or read how a SaaS company de-identifies 13M+ long texts a day.
Frequently asked questions
What is an example of de-identification?
Replacing a patient’s name, record number and admission date in a clinical note with tokens, while keeping the diagnosis and treatment as written. The note still teaches a model or an analyst something, but it no longer names the patient.
Is de-identified data still personal data?
It depends on the method and the law. Pseudonymized data is still personal data under GDPR. Data de-identified under HIPAA Safe Harbor or Expert Determination is no longer PHI. Truly anonymized data falls outside most privacy laws.
What is the difference between data masking and de-identification?
Masking is one de-identification method. It hides part or all of a value. De-identification is the broader goal and can use masking, tokenization, generalization, suppression or a mix.
What should a de-identification tool do?
Find identifiers in both tables and free text, support custom identifiers, offer reversible and permanent modes, keep tokens consistent across datasets, run inside your pipelines, and log who saw real values. For health data, compare options in best PHI de-identification tools.